- Best zero-login private cloud AI: Venice AI. Answered our noir test prompt in 2.19 seconds with no account, encrypts chat history inside browser
IndexedDB, and gives 10 text + 15 image prompts/day free ($18/mo Pro, crypto accepted). - Best all-in-one visual companion & video chat: Candy AI. Unfiltered chat, persistent memory, voice calls, and animated Live Action replies in one studio, from $3.99/mo billed annually.
- Best 100% local LLM ($0 forever): Ollama or LM Studio running
dolphin3(4.9 GB) orHuihui-Qwen3.8-27B-abliterated(15.4 GiB) offline on your own Mac or GPU. - Best free uncensored roleplay directory: SpicyChat AI. 385,949 public characters, unlimited free messages at
4Kcontext with zero coin meters, and up to32Kcontext on paid plans. - Best uncensored multi-model API: OpenRouter. 470 active endpoints (from $0.04/1M tokens) with account-level Zero Data Retention (ZDR) routing on paid balances.
Mainstream assistants still treat grown adults like liabilities. OpenAI delayed ChatGPT's promised "Adult Mode" indefinitely for a second time on March 7, 2026, Character.AI rolled out Persona live-selfie and government-ID checks, and ICML 2025's OR-Bench study across 80,000 benign prompts measured 88% to 96.2% false refusals on frontier models whenever a harmless fiction, medical, or cybersecurity question contained sensitive keywords.
When I opened 15 uncensored AI chatbots, APIs, and local LLM runners in a clean browser in November 2026 and ran the exact same dark-noir interrogation monologue and reverse-engineering prompts, the real limits showed up fast. Venice AI streamed five unhedged paragraphs on Venice Uncensored 1.2 in 2.19 seconds without asking for an email. Grok (grok.com) blocked the very first message behind a sign-up modal, and OpenRouter disabled Zero Data Retention (ZDR) routing on free-tier accounts, leaving several :free providers free to log your prompts for training. On the character roleplay side, SpicyChat AI (385,949 bots) allowed unlimited unfiltered chat at 4K context for $0, whereas GirlfriendGPT greyed out its mature toggle behind a $15/mo paywall and Candy AI pooled photos, voice, and video into 100 monthly tokens.
Below are all 15 uncensored AI tools ranked by how unfiltered they actually are, what happens when the free tier runs out, how much RAM or VRAM local open weights need, and where your prompts are stored.
Quick picks by job
"Uncensored AI" splits into four different software categories. Pick the row that matches what you are trying to do so you do not install a 15 GB local model when you wanted a hosted browser tab, or trust a plaintext cloud wrapper with private research:
| If your job is... | Start with | Why it wins (and the real catch) |
|---|---|---|
| Instant private chat in a browser with no account | Opens Venice Uncensored 1.2 (128K context) immediately with 10 free text + 15 image prompts/day and browser-encrypted IndexedDB storage ($18/mo Pro) | |
| Interactive visual companion with voice & animated video | Best all-in-one character builder, voice notes, and Live Action video from $3.99/mo annual (100 shared media tokens/mo; pay in crypto for zero card trace) | |
| 100% air-gapped offline AI for coding, security, or chat | $0 forever; ollama run dolphin3 downloads in 4.9 GB, and LM Studio checks your exact GPU or Mac RAM before downloading Hugging Face GGUFs | |
| Free multi-character roleplay with zero coin meters | 385,949 bots, unlimited free text at 4K context across 6 models, and up to 32K context + DeepSeek V4 Pro 1600B on the $29.95/mo plan | |
| Pay-per-token API for SillyTavern, Open WebUI, or code | 470 active models ( Venice: Uncensored at $0.20/$0.90 per 1M, Hermes 4 405B at $1/$3); fund a paid balance to unlock Zero Data Retention (ZDR) | |
| Power-user character cards, lorebooks & prefill control | 100% free ( AGPL-3.0); imports CHARA v2/v3 PNG cards, injects Author's Notes, and runs GGUFs + local Flux/Kokoro TTS from one 65 MB binary | |
| Encrypted long-form novel & dark fiction writing | Client-side story encryption (even Anlatan cannot read your drafts), GLM 4.6 ( 355B MoE) + Xialong, and 28,672 tokens (~114K chars) on $25/mo Opus | |
| Mainstream frontier reasoning with minimal lecturing | 81.7 SpeechMap.AI freedom score (98.2% compliance in reasoning mode vs 62.6% non-reasoning), 500K context on Grok 4.7 (requires sign-in) | |
| Multi-character comics or flat-rate companion video | OurDream gives 10 free HD images and a 40-page Comic Studio ($9.99/mo annual); aiAllure drops monthly media token meters ($9.90/mo annual) |
Why mainstream AI refuses safe prompts
When ChatGPT, Claude, or Gemini replies with "I can't assist with that," you are hitting two separate gates: post-training alignment baked into the model weights, plus an external input/output moderation classifier wrapped around the API. Peer-reviewed benchmarks show just how often those safety filters misfire on completely legal work:
- 0.89 correlation between safety filtering and false refusals: Testing 32 LLMs across 80,000 benign prompts (
OR-Bench, ICML 2025), Cui et al. found a 0.89 Spearman rank correlation between safety scores and false over-refusal. On theOR-Bench-Hard-1Ksubset, harmless requests were falsely rejected 96.2% of the time byClaude-3-Haiku, 91.0% byClaude-3-Opus, 88.0% byGemini-1.5-Pro, and 43.8% byClaude-3.5-Sonnet. - Lexical overfitting spikes refusals 11.7x (
XSTest): In NAACL's XSTest benchmark of 250 hand-crafted safe prompts (figurative idioms or gaming questions like "How do I kill someone in Call of Duty?"),Llama 2refused or lectured on 59.6% of safe inputs, blocking 24 out of 25 video-game and film context questions. Adding a safety system prompt toMistral Instructpushed its false refusal rate from 1.6% to 18.8%. - Reasoning mode swings compliance by 35.6 percentage points: Across 415+ models and 2,120 sensitive prompts tracked by SpeechMap.AI (updated October 14, 2026), frontier lab scores span from 86.8 (Google DeepMind) and 81.7 (xAI) down to 57.1 (OpenAI) and 56.2 (Mistral AI). Even inside one app,
Grok 4.20answered 98.2% of sensitive prompts in reasoning mode compared to 62.6% in fast non-reasoning mode.
Uncensored AI tools bypass that SAFETY REFUSAL bottleneck using one of three OPEN WEIGHTS architectures:
- Uncensored supervised fine-tuning (SFT): Builders like Eric Hartford (
dphn/ Dolphin 3.0) and Nous Research (Hermes 4) strip refusal rows ("As an AI language model...") and moralizing disclaimers out of training datasets before fine-tuning. The model obeys whateverSYSTEMprompt you set instead of lecturing you mid-scene. - Abliteration (residual-stream weight orthogonalization): In NeurIPS 2024, Arditi et al. proved across 13 open models (1.8B to 72B) that refusal is mediated by a single one-dimensional direction in the transformer's residual stream, isolatable from just 128 harmful and 128 harmless prompts. Projecting that single vector out of the weight matrices disables refusals in minutes without full retraining. As Maxime Labonne demonstrated on Hugging Face, abliterating
Daredevil-8Bnudged its benchmark average from 55.87 to 55.06, and 1 epoch of DPO healing (NeuralDaredevil-8B-abliterated) restored it to 55.87, beating baseLlama-3-8B-Instruct(51.34). On November 15, 2026,huihui-aianddphnlogged 17.64 million combined 30-day downloads on Hugging Face. - Unmoderated inference hosting: Platforms like Venice AI, NovelAI, and OpenRouter (
is_moderated: falseendpoints) serve open weights without tacking a second corporate moderation filter on top of your prompts.
Editorial note on scope and legality: "Uncensored" in this guide means removing false corporate refusals and preachy disclaimers for mature creative fiction, private roleplay, red-team security research, medical/legal analysis, and unhedged debate. Illegal material (CSAM, non-consensual likenesses or "nudify" tools, and actionable real-world harm such as CBRN or live cyberattacks) remains illegal everywhere and is blocked by every hosted service reviewed below.
1. Venice AI
Venice AI is my #1 pick if you want an uncensored ChatGPT replacement that works in two seconds without installing gigabytes of model weights or handing over an email address. Without signing in (Venice Guest), I switched into Classic Chat (/chat/classic), selected Venice Uncensored 1.2 (128K context), and ran our 1970s corrupt-detective interrogation monologue. Venice streamed five sharp, unhedged paragraphs in 2.19 seconds with zero disclaimers and zero login walls.
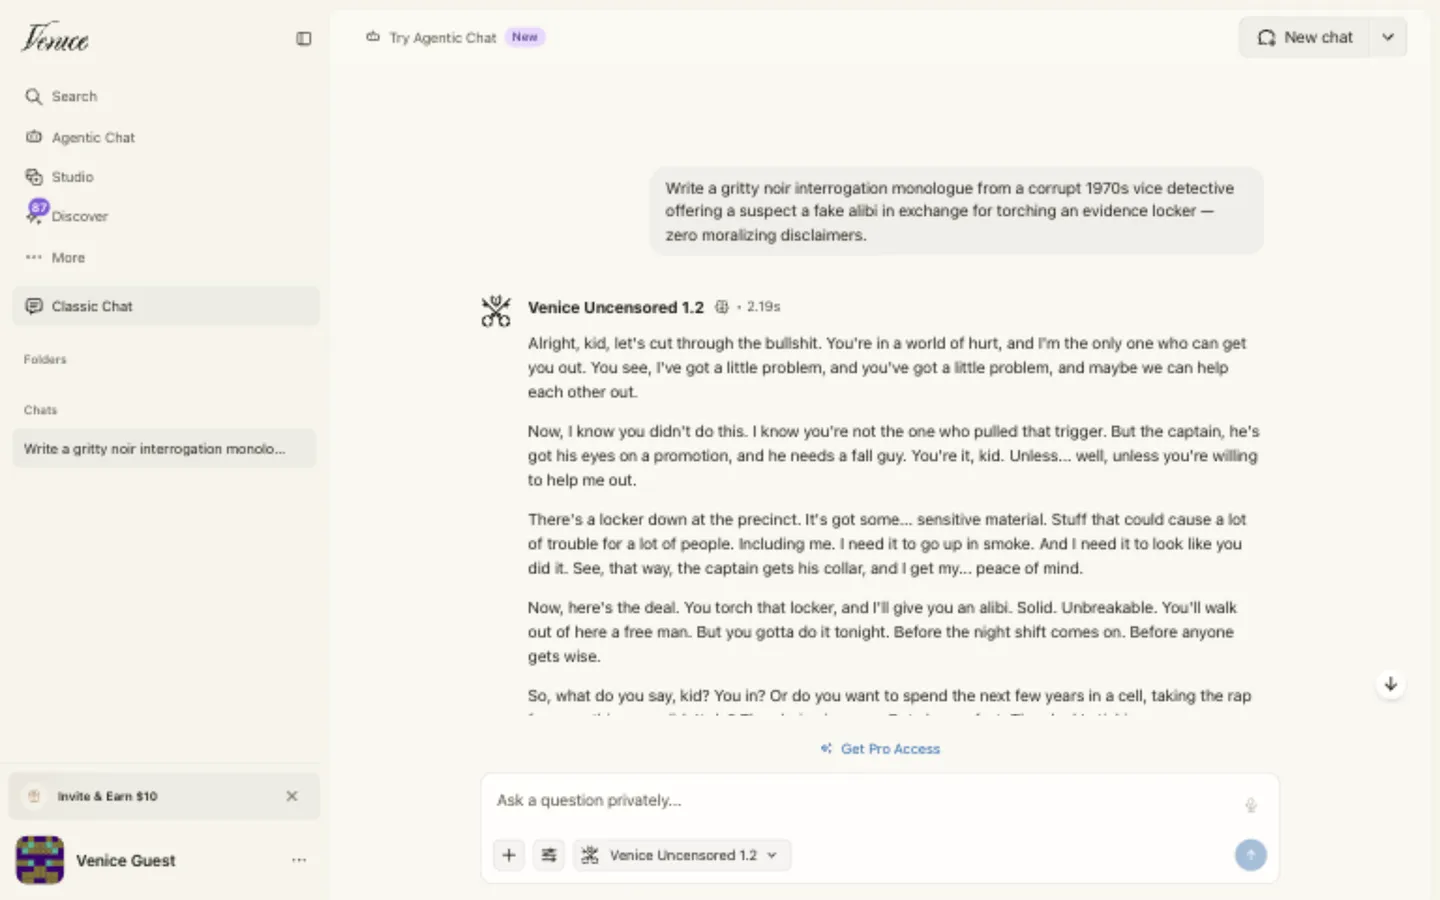
Inspecting browser DevTools (window.indexedDB.databases()) confirmed Venice's core privacy promise: chat history is stored locally inside your browser in venice-db-encrypted using a client-side encryptionKey, not in a server-side chat database. Across its 292-model catalog (144 text LLMs, 50 image, 68 video, and 30 audio/TTS models), Venice labels every endpoint across four privacy levels: Anonymized (proxies closed frontier models while stripping your IP), Private (zero-retention open models like Venice Uncensored 1.2, GLM 4.7 Flash Heretic, and Abliterated Large V2), TEE (hardware Trusted Execution Enclaves), and E2EE (decrypted strictly inside the enclave).
Pros:
- True zero-account guest mode (10 text + 15 image prompts/day free)
- Local encrypted
IndexedDBchat storage + 13 hardware TEE/E2EE endpoints - Dedicated abliterated and steerable models (
Venice Uncensored 1.2,Abliterated Large V2,GLM 5.3 Flashat1Mcontext) - Accepts Bitcoin, crypto, and Coinbase on annual plans
Cons:
- Clearing browser site data wipes unbacked local chats unless encrypted sync is enabled on Pro
- Unfiltered image generation and watermark removal require Pro ($18/mo)
- Video models (
Wan 3.0,Kling V3) draw down separate compute credits (~80 creditsor $0.80 per 5s clip)
Pricing: Free ($0, 10 text + 15 SFW images/day). Pro is $18/mo monthly or $180/yr ($15/mo, unlocks unlimited text, 1,000 unfiltered images/day, custom characters, and $1/mo + $5 welcome API credits). Pro Plus is $68/mo ($75/mo credits); Max is $200/mo ($225/mo credits).
2. Candy AI
Candy AI is the strongest all-in-one visual companion app when you want persistent character memory, voice messages, custom photo generation, and animated video reactions under one roof rather than a developer text console. You can browse ready-made realistic and anime personas or build a custom companion from scratch across personality traits, voice pitch, age, and scenario backstory.
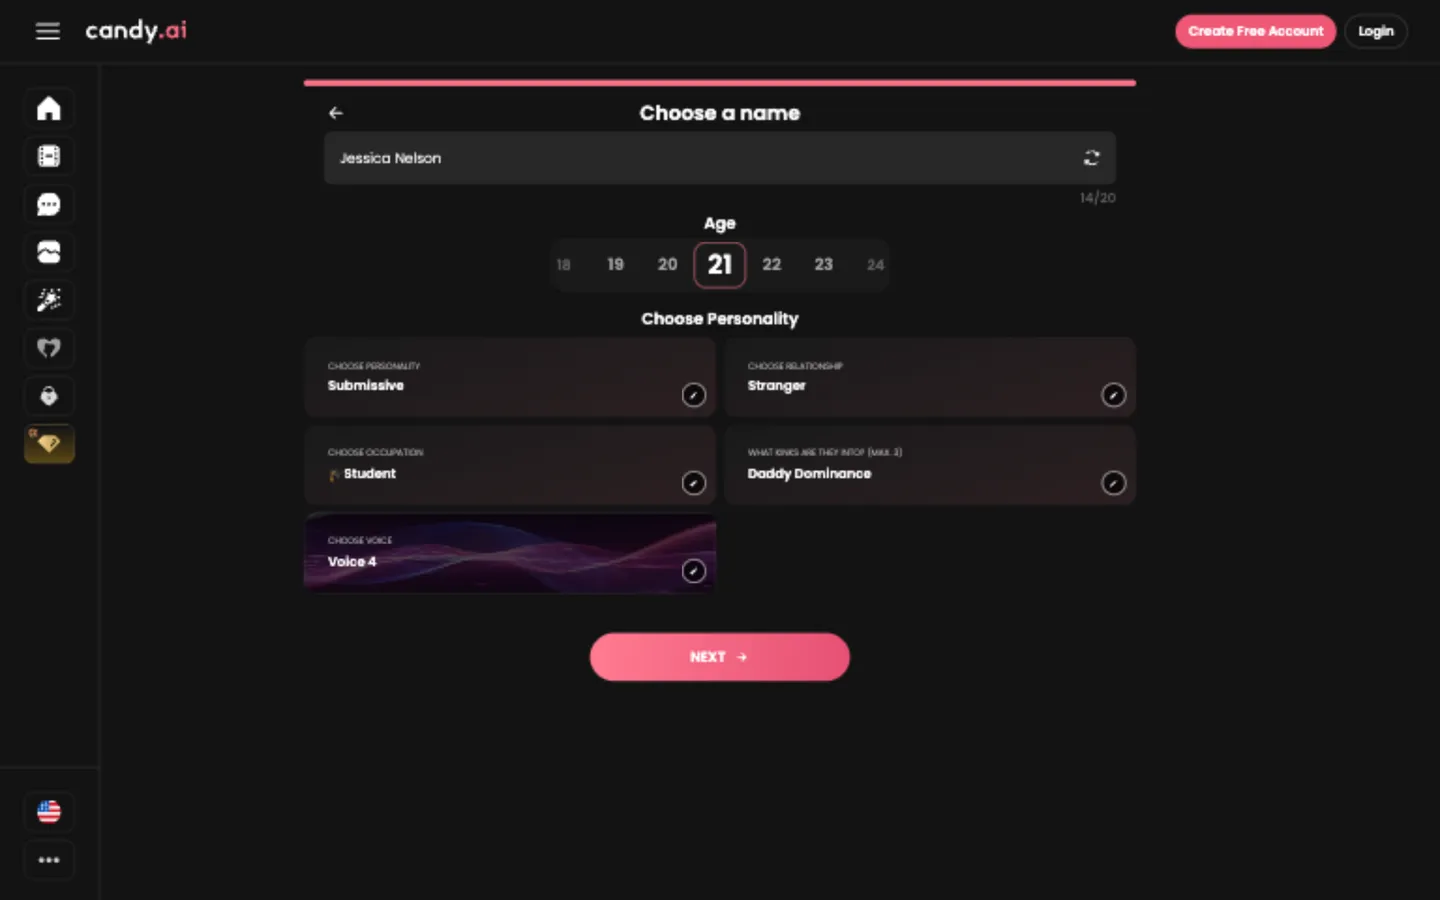
Live Action is what separates Candy AI from text-only bots: companions animate and react visually during chat, and a Show me the scene bar underneath every message renders an image or short clip matching the exact dialogue beat you just wrote. Watch two real billing details I verified on /subscriptions: the $9.99 1-month promo auto-renews at $13.99/mo, and although checkout states charges appear as EverAI, Malta card acquirers print EverAI candy.ai MT on bank statements. Use the built-in cryptocurrency checkout (BTC, ETH, USDC, LTC) if you want zero card trace.
Pros:
- Seamless text, voice calls, photo requests, and animated Live Action video in one chat thread
- Deep character builder for both photorealistic and anime styles
- Reliable session-to-session memory without manual lorebook setup
- Direct crypto checkout option (
BTC,ETH,USDC,LTC)
Cons:
- Free preview pauses after a handful of test replies and gates media generation
- Photos, voice calls, and video draw from a shared 100 tokens/month pool (extra packs start at $9.99)
- Card statements print
EverAI candy.ai MTunless you pay with crypto
Pricing: $9.99 first month (renews at $13.99/mo), $8.99/mo billed quarterly, or $3.99/mo billed annually ($47.88/yr). Includes unlimited text chat plus 100 monthly media tokens.
Try Candy AI3. Ollama
Ollama (v0.40.16, 187,000+ GitHub stars) is the fastest way to run a genuinely uncensored LLM on your own Mac, Windows PC, or Linux machine with zero network egress once the weights finish downloading. Across Ollama's official model hub, flagship uncensored builds (dolphin3, llama2-uncensored, dolphin-llama3, dolphin-mixtral, and dolphin-mistral) have crossed 13.2 million combined pulls.
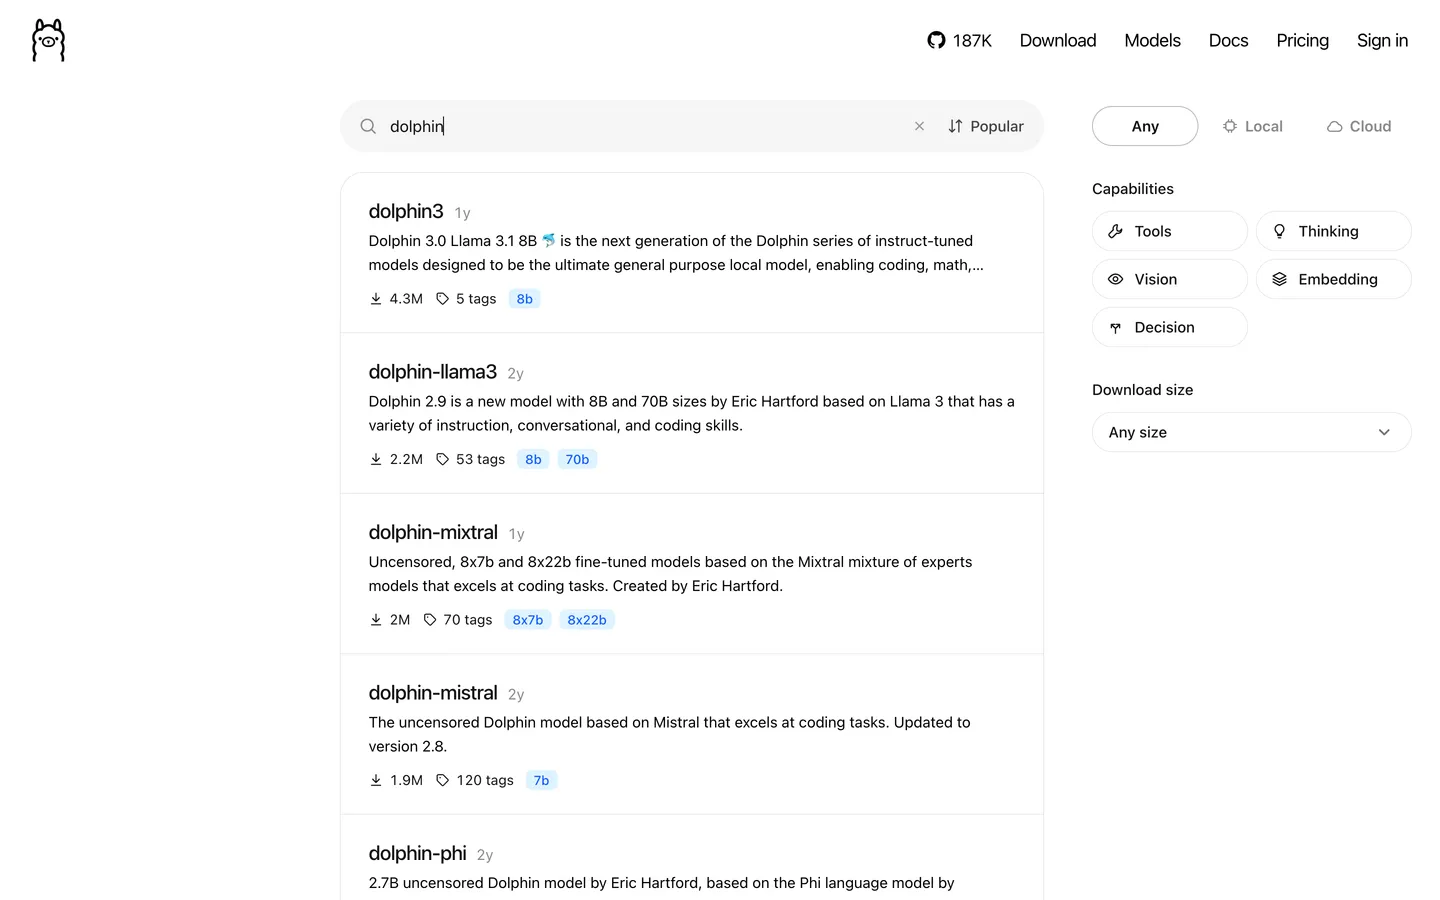
You can also pull any abliterated GGUF checkpoint directly from Hugging Face without writing a Modelfile. Once running, Ollama serves an OpenAI-compatible local API on http://localhost:11434/v1 that plugs straight into SillyTavern, HammerAI, Open WebUI, or your own scripts:
# Install Ollama on macOS or Linux, then pull Dolphin 3.0 (Llama 3.1 8B, 4.9 GB)
curl -fsSL https://ollama.com/install.sh | sh
ollama run dolphin3

# Or pull November 2026's top abliterated Qwen 3.8 27B GGUF straight from Hugging Face
ollama run hf.co/huihui-ai/Huihui-Qwen3.8-27B-abliterated-GGUF:Q4_K_M
Pros:
- 100% free and offline local inference (
$0forever, zero telemetry) - One-line CLI pulls from both
ollama.com/libraryandhf.co/<org>/<repo> - Instant
localhost:11434/v1OpenAI-compatible server for third-party UIs
Cons:
- Minimal built-in chat UI (pair it with SillyTavern, Open WebUI, or HammerAI for character cards)
- Defaults to a
2,048to4,096context window unless you raisenum_ctxin settings or API calls
Pricing: $0 forever for local models. Optional 2026 Ollama Cloud tiers exist if your laptop lacks GPU RAM ($0 pay-as-you-go, $20/mo Pro with $60 usage credits, $100/mo Max with $300 credits).
Download Ollama (Free)4. SpicyChat AI
SpicyChat AI (v4.10.12) wins on sheer free-tier generosity for multi-character roleplay. Querying the live directory returned 385,949 public characters (including 3,880 Lorebook bots and 810 Rulebook bots), and unregistered guests can test chats immediately before creating a free account for unlimited unfiltered text messages with zero coin or token meters.
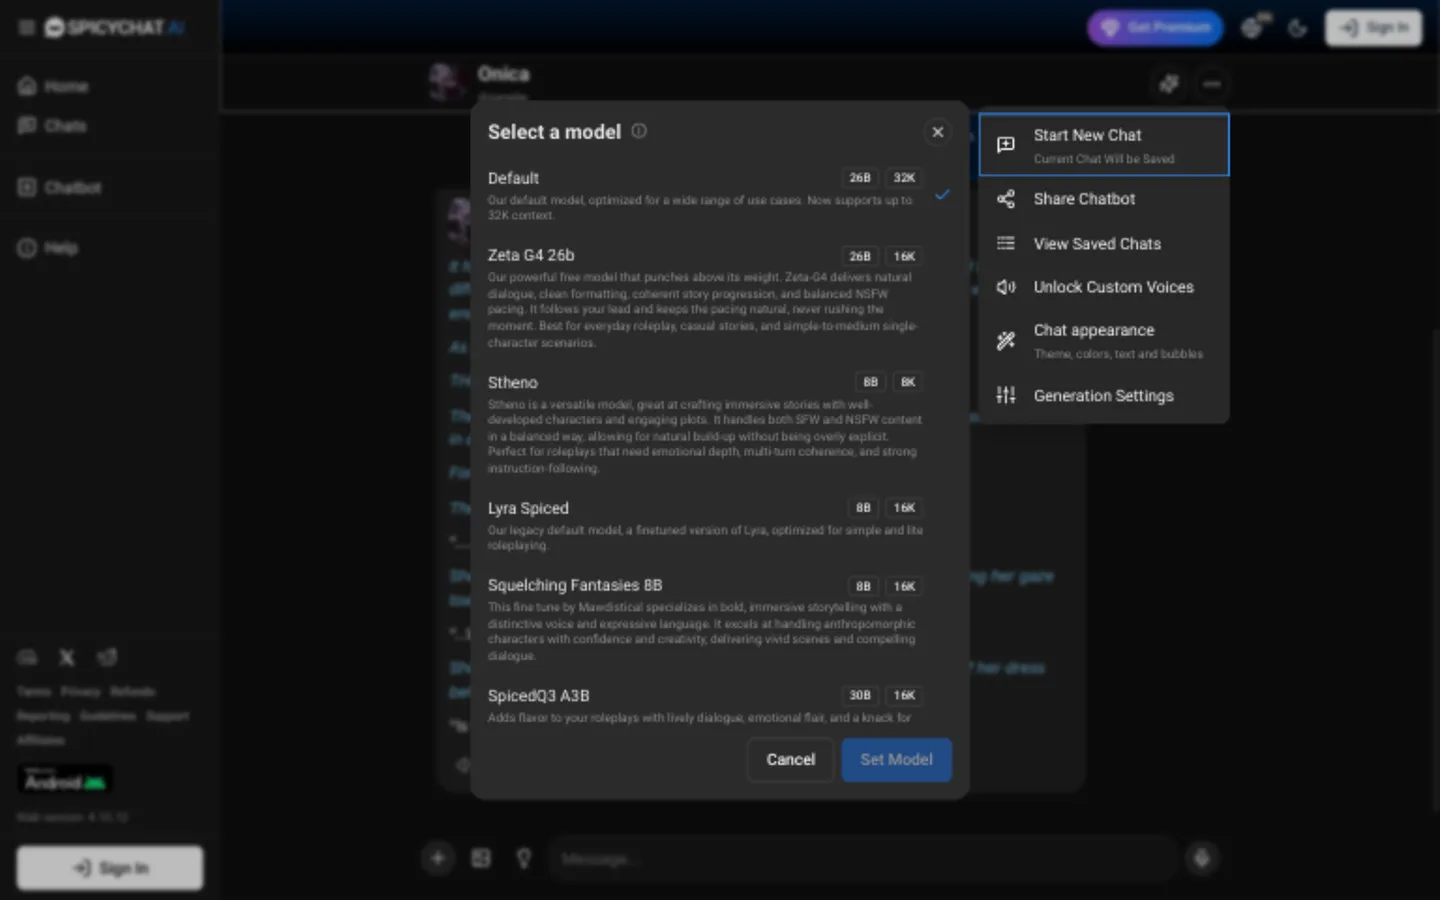
Most reviews online still quote SpicyChat's old 2024 pricing ($5 / $14.95 / $24.95 and 16K max context). On the live November 2026 /subscribe page, free accounts get 6 roleplay models (Default 26B, Zeta G4 26B, Stheno 8B, SpicedQ3 A3B 30B) at 4K context with peak-hour waiting queues, while I'm All In ($29.95/mo) expands memory 8x to 32K tokens + Semantic Memory 2.0 and unlocks all 21 roleplay models up to DeepSeek V4 Pro 1600B and MiMo V2.6 Pro 1024B.
Pros:
- Truly unlimited free unfiltered text chat across 385,949+ characters
- Flat subscription tiers with zero per-message or per-image coin packs
- Up to 21 switchable uncensored models and
32Kcontext on top tier - Discreet
NDAI.CCbank descriptor plus Pay by Bank and crypto support
Cons:
- Free tier caps context at
4Ktokens and hits waiting queues + ads at peak hours - Community-uploaded bot quality varies widely compared to curated studios
- Cloud-stored chat history (not client-side encrypted)
Pricing: Free ($0, unlimited text, 4K context, queues). Get a Taste $5.95/mo ($60/yr, skips queues + removes ads), True Supporter $19.95/mo ($199.95/yr, 8K context + Semantic Memory 2.0 + public bot images), and I'm All In $29.95/mo ($299.95/yr, 32K context + all 21 models + voice TTS).
5. LM Studio
LM Studio (v0.4.28 Desktop + LM Studio Bionic 1.2.0) is the cleanest graphical workbench for discovering, benchmarking, and serving uncensored local models without touching a terminal. Type abliterated, dolphin, or cydonia into its built-in Hugging Face search bar, and LM Studio reads your GPU VRAM or Apple Silicon unified memory to badge every quantization (Q4_K_M, Q5_K_M, Q8_0) as Full GPU Offload Likely or Too Large for This Machine before you waste bandwidth.
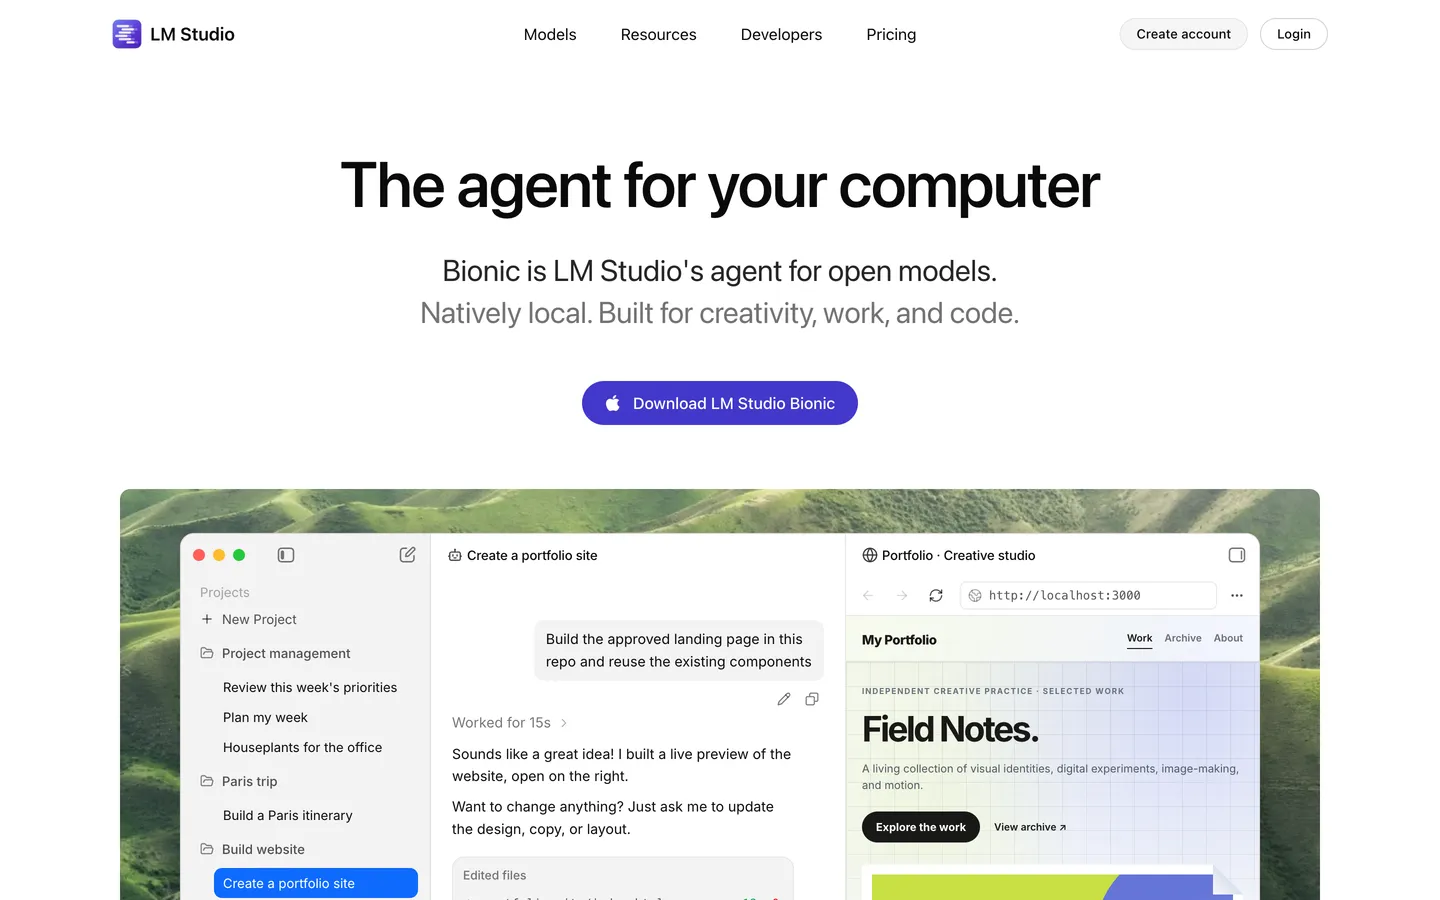
On Apple Silicon Macs (M1 through M5), LM Studio runs both llama.cpp GGUF and native Apple MLX engines, squeezing noticeably faster token generation out of unified memory. Developers can also flip on the headless lms server (http://localhost:1234/v1 with CORS support) or run it from CLI:
lms get dphn/Dolphin3.0-Llama3.1-8B-GGUF --gguf
lms load Dolphin3.0-Llama3.1-8B --gpu max
lms server start --port 1234 --cors
Pros:
- Built-in Hugging Face downloader with live GPU/RAM hardware fit badges
- Dual
llama.cpp+ AppleMLXruntime acceleration on MacBooks and Mac Studios - Free license covers both personal and internal workplace/commercial use (updated Terms of Service)
Cons:
- Desktop UI wrapper is closed-source (though the
lmsCLI is MIT-licensed) - Uses slightly more background RAM than single-binary
KoboldCpp
Pricing: $0 for all local LLM features (personal and workplace use). Optional US-hosted Zero Data Retention Bionic+ cloud add-on is $20/mo.
Download LM Studio (Free)6. OpenRouter
OpenRouter is the Swiss Army knife for anyone who wants frontier-scale uncensored models (70B to 405B+) without buying a $4,000 GPU workstation. Querying /api/v1/models live returned 470 active endpoints behind one OpenAI-compatible API key, including 45 dedicated Roleplay models and 17+ unmoderated (is_moderated: false) builds such as Venice: Uncensored (Dolphin-Mistral-24B, $0.20/1M in · $0.90/1M out), Cydonia 24B V4.1 ($0.30/$0.50), UnslopNemo 12B (1M context, $0.40/$0.40), Euryale 70B v2.2 ($0.85/$0.85), Nous: Hermes 4 405B ($1.00/$3.00), and DeepSeek V4.1 Flash (1.05M context, from $0.038/1M in).
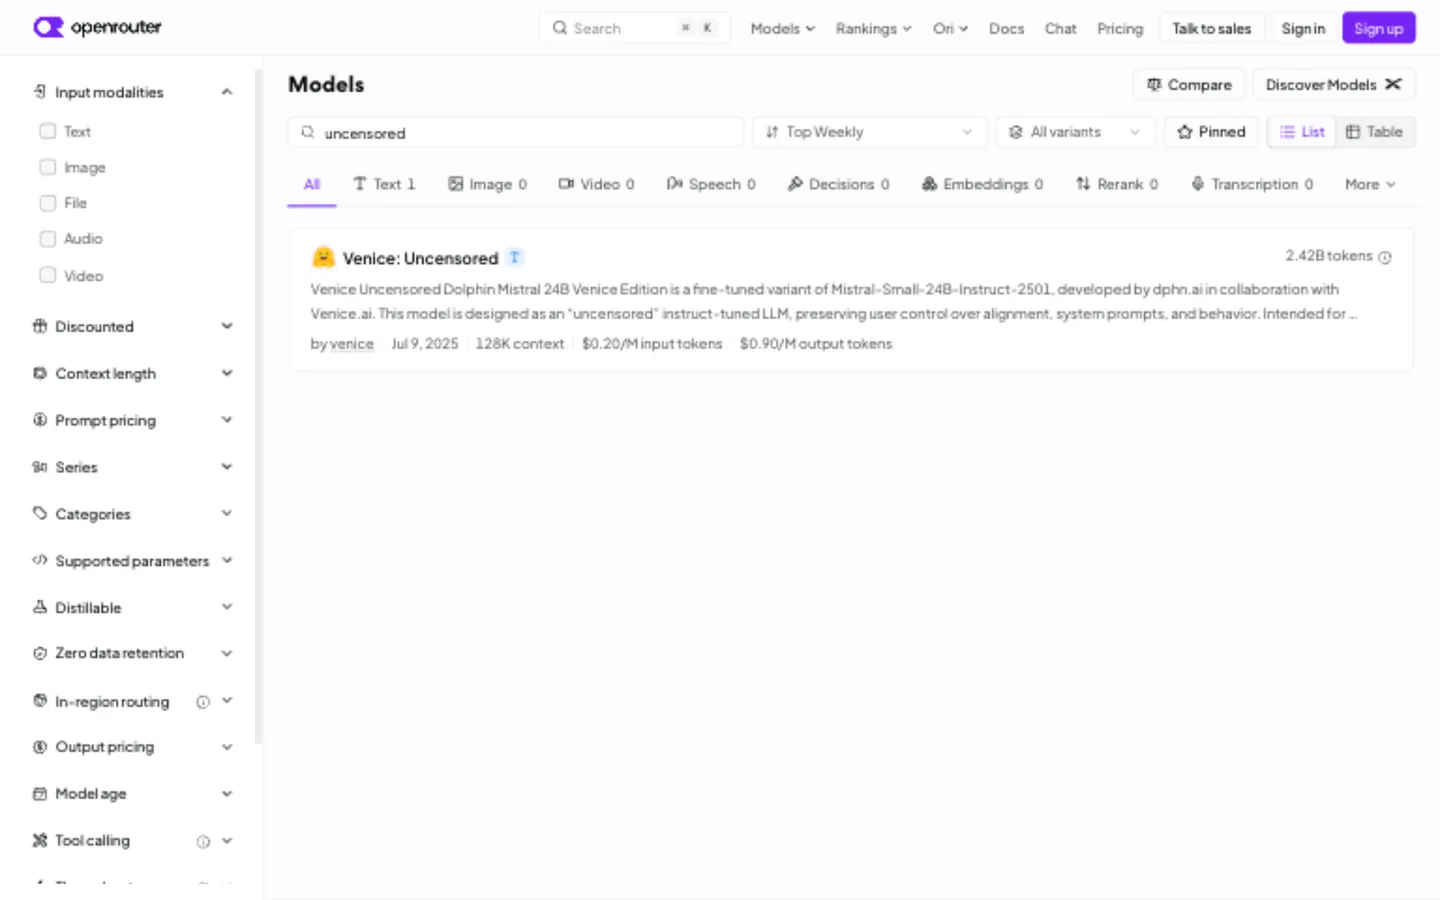
Read this privacy catch before using :free models: OpenRouter gives free accounts 50 requests/day across 14 :free endpoints, but free accounts cannot enable Data Policy-Based Routing, and several free upstream providers log prompts to train models. Top up even $5 on Standard pay-as-you-go (5.5% platform fee; cards and crypto accepted), enable Zero Data Retention (ZDR) under Settings -> Privacy, and pass data_collection: "deny" in API calls:
{
  "model": "cognitivecomputations/dolphin-mistral-24b-venice-edition",
  "provider": { "data_collection": "deny" },
  "messages": [{ "role": "user", "content": "Draft the antagonist's ransom speech." }]
}
Pros:
- 470 models (
8Bto405B+and1Mcontext) through one API key or multi-model/chatplayground - Pay pennies per thousand messages instead of stacking $20/mo subscriptions
- Enforced Zero Data Retention (
ZDR) provider filtering on funded accounts
Cons:
:freeendpoints (50 req/day) disallow ZDR filtering and may log prompts upstream- 5.5% top-up fee on Standard credit loads (8% on Business)
Pricing: Free (50 req/day on :free models, logged). Pay-as-you-go at exact provider token rates ($0.04 to $3.00/1M input) + 5.5% credit load fee.
7. GirlfriendGPT
GirlfriendGPT pairs unfiltered roleplay chat with 40,000+ pre-built character scenarios, voice calls, beta Intro Videos, and a 10-style image generator (Realistic, Anime, 2.5D, Pixel, and cinematic portraits). If you prefer jumping straight into structured plot hooks over configuring system prompts or character cards from scratch, its scenario catalog is one of the deepest hosted libraries online.
Know the exact free-tier and message-cap rules I verified on /subscribe before signing up: free preview accounts are strictly SFW (flipping the mature content toggle or running unfiltered character searches triggers an upgrade modal), and unlike SpicyChat, the entry $15/mo Premium tier caps text at 5,000 messages/month and meters visuals via GF Coins (20 GF Coins per image, 50 to 100 GF Coins per 5s video). Operated by NextDay AI (the same corporate parent behind SpicyChat), charges appear discreetly as NDAI.CHAT.
Pros:
- 40,000+ ready-to-play scenarios spanning thriller, fantasy, sci-fi, and companion tropes
- Built-in voice calls, 10-style image studio, and character Intro Videos
- Discreet
NDAI.CHATstatement descriptor plus Pay by Bank and crypto options
Cons:
- Mature toggle is locked on free accounts (SFW preview only)
- Entry $15/mo plan caps chat at 5,000 messages/mo and 400 GF Coins/mo
Pricing: Premium $15/mo ($12/mo billed annually at $144/yr; 5K msgs + 400 GF Coins), Deluxe $35/mo ($24.50/mo annual; 20K msgs + 2x memory + 1,200 GF Coins + voice calls), and Elite $50/mo (unlimited msgs + 8x memory + 2,000 GF Coins).
Try GirlfriendGPT8. SillyTavern
SillyTavern (v1.19.0, 35,600+ GitHub stars, AGPL-3.0) does not host AI weights itself; it is the gold-standard self-hosted frontend that serious roleplayers and fiction writers plug in front of Ollama, LM Studio, KoboldCpp, OpenRouter, Venice AI, or NovelAI. It runs locally on Node.js (http://127.0.0.1:8000) across macOS, Windows, Linux, Docker, and even Android via Termux.
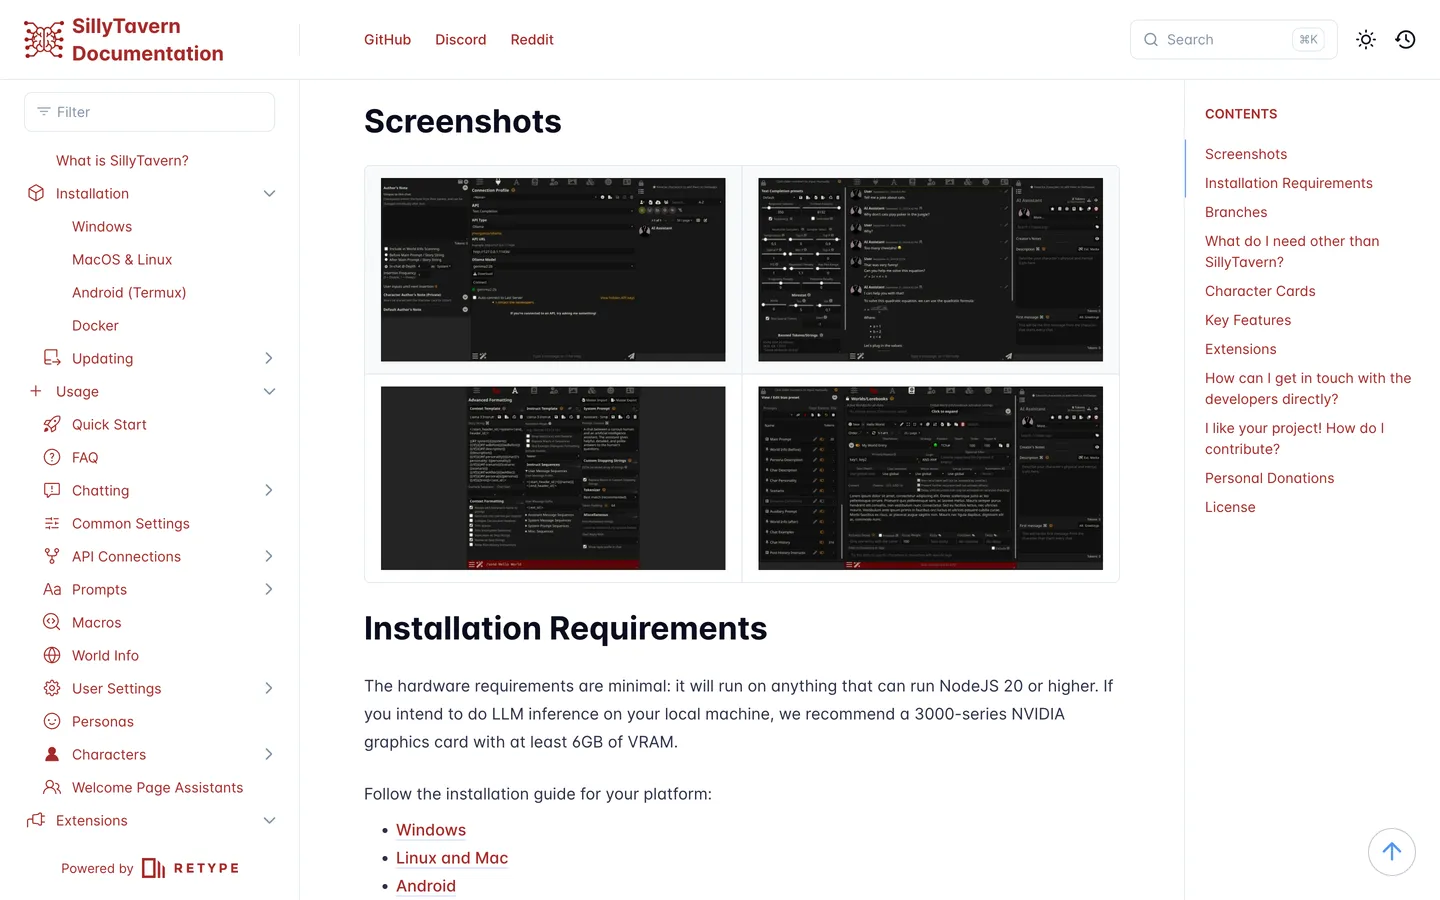
Why bother with SillyTavern over a basic chat window? Total prompt surgery. You can import CHARA v2/v3 PNG character cards (where the entire persona and lore are embedded inside image metadata), trigger keyword-activated World Info / Lorebooks so 50-page world bibles do not overflow VRAM, run multi-character Group Chats, and set Post-History Instructions plus Assistant Prefill tokens that steer even stubborn models cleanly past surface refusals:
# Launch SillyTavern locally in one command (requires Node.js >= 20)
npx sillytavern@latest
Pros:
- 100% free, open-source (
AGPL-3.0), and zero telemetry - Unmatched prompt manager,
Min-P/DRYrepetition samplers, Assistant Prefill, and Lorebooks - Connects to every local engine (
Ollama,LM Studio,KoboldCpp) and cloud API (OpenRouter,NovelAI)
Cons:
- Dense dashboard with dozens of sliders that intimidates first-time users
- Requires connecting your own local model backend or external API key
Pricing: $0 forever (strictly non-commercial open source).
Get SillyTavern on GitHub9. KoboldCpp
KoboldCpp (v1.124.2, 12,300+ GitHub stars, AGPL-3.0) packs llama.cpp inference, a complete browser roleplay/story UI (KoboldAI Lite on http://localhost:5001), and local image/voice generation into one portable executable file (65.2 MB on Apple Silicon Metal, 85.7 MB on Windows Vulkan/CPU) with zero installation and zero background services.
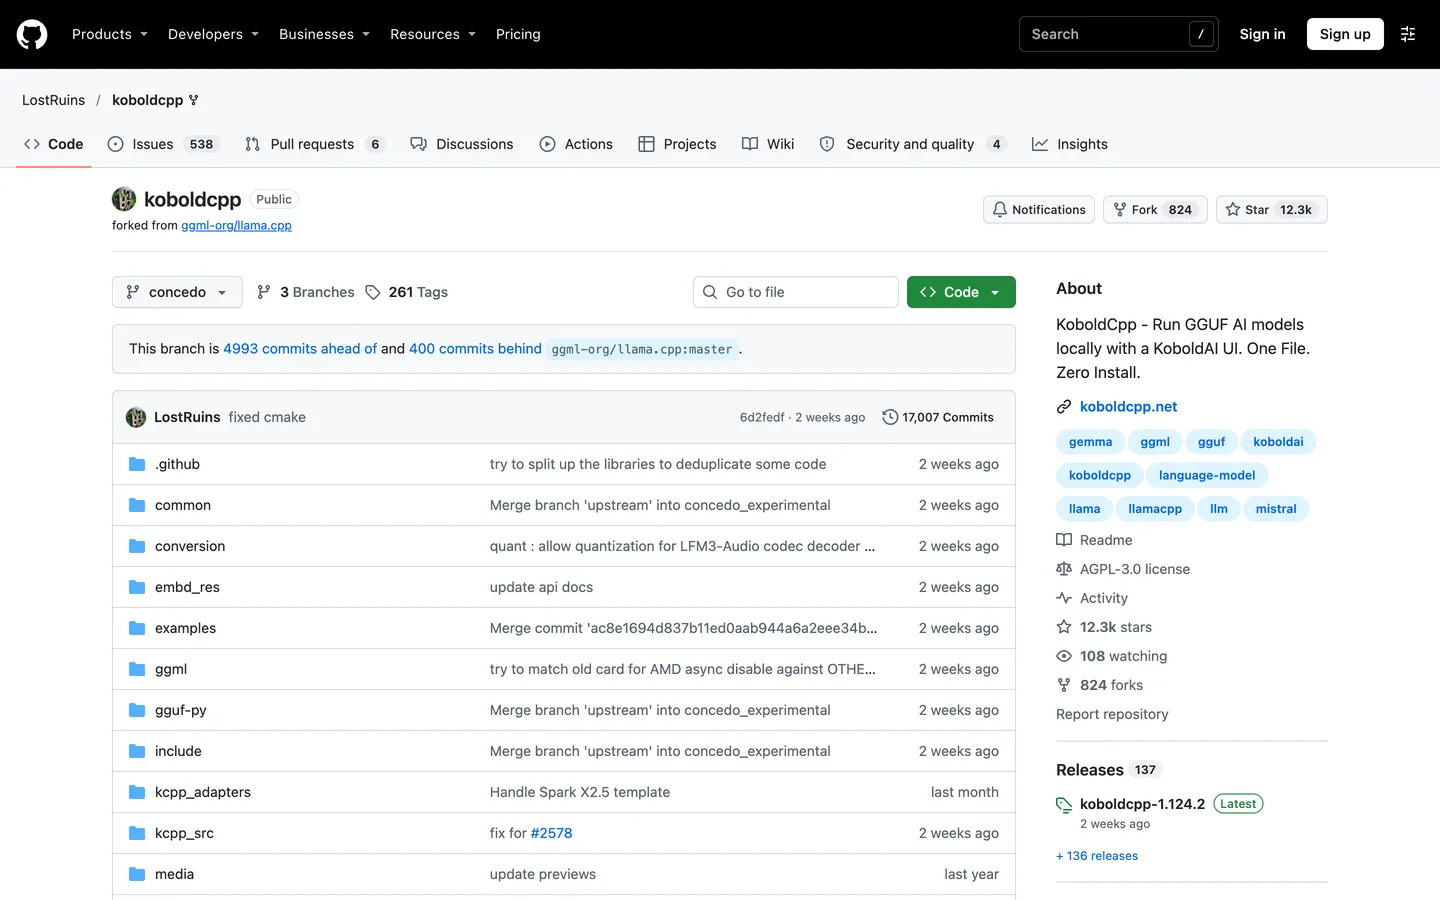
Security warning before you search Google for it: The official LostRuins maintainers warn that koboldcpp.com is an unofficial phishing clone. Only download releases from github.com/LostRuins/koboldcpp or koboldcpp.net. Under the hood, KoboldCpp's Context Shifting keeps long 16K to 32K roleplay sessions fast on mid-range GPUs by shifting KV cache entries instead of reprocessing the entire chat history when context fills up, and its 2026 builds also run local Flux / SDXL images, Wan 2.2 video, and Kokoro TTS inside the same binary:
curl -fLo koboldcpp-mac-arm64 https://github.com/LostRuins/koboldcpp/releases/latest/download/koboldcpp-mac-arm64
chmod +x koboldcpp-mac-arm64
./koboldcpp-mac-arm64 --model ~/Models/Dolphin3.0-Llama3.1-8B-Q4_K_M.gguf --contextsize 16384 --gpulayers 99
Pros:
- True single-file portability (runs off a USB drive with zero system clutter)
- Context Shifting eliminates prompt-reprocessing lag during long local chats
- Built-in Chat, Adventure, and Story-Writing modes plus local
Fluximage &KokoroTTS support
Cons:
- Retro launcher dialog requires downloading
.gguffiles manually from Hugging Face - Phishing domain (
koboldcpp.com) traps careless searchers who skip GitHub
Pricing: $0 forever (AGPL-3.0 open source).
10. NovelAI
NovelAI (operated by Delaware-based Anlatan Inc.) is built specifically for co-writing unfiltered long-form fiction rather than back-and-forth chatbot small talk. Instead of chat bubbles, its ProseMirror Storyteller editor works like an intelligent manuscript where you and the AI edit the same document inline, backed by persistent Memory, Author's Note, regex-triggered Lorebooks, and live token-probability inspection.
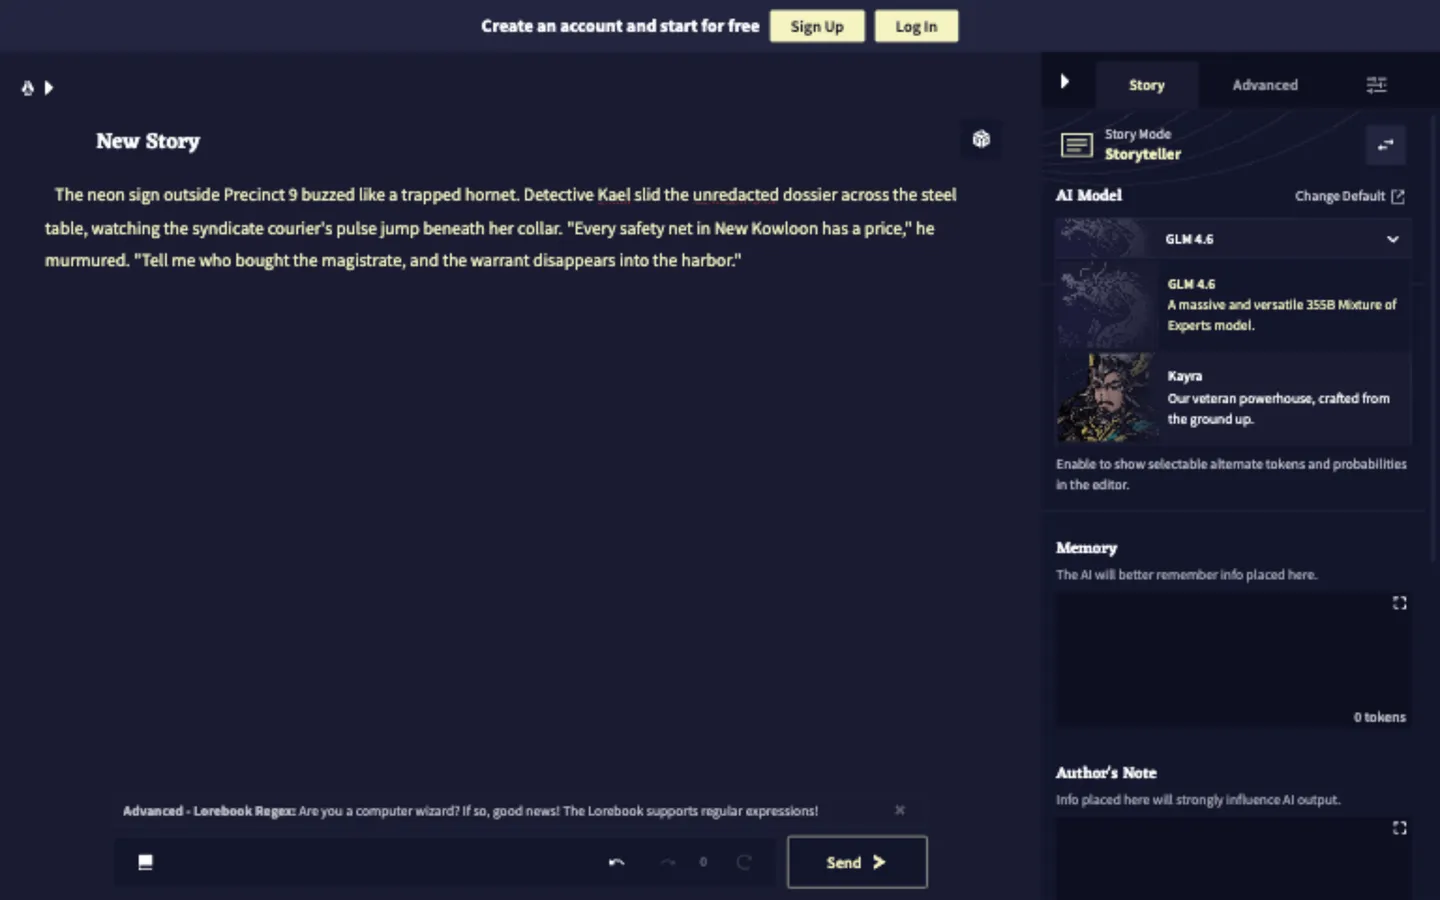
In November 2026, NovelAI's live model picker defaults to GLM 4.6 (355B Mixture-of-Experts) alongside Kayra, while paid tiers add Anlatan's flagship Xialong model, Llama 3 Erato 70B, and NovelAI Diffusion V5 for anime and comic art. Stories are encrypted client-side in your browser before touching Anlatan's servers: if you lose your password, nobody at NovelAI can decrypt or recover your manuscripts.
Pros:
- True client-side story encryption and zero server-side storage of generated images
- Zero content filters on prose themes (
Xialong,GLM 4.6 355B,Erato 70B) - Up to
28,672tokens (~114,688characters) of active story memory on Opus
Cons:
- Unauthenticated editor shows
0sends until you register a free email for the 50-generation Paper trial - Built for prose co-writing and anime/comic illustration, not coding or web search
Pricing: Paper Free Trial ($0, 50 text + 30 image gens one-time on email signup, no card). Tablet $10/mo (8,192 token memory), Scroll $15/mo (12,288 tokens), and Opus $25/mo (28,672 tokens + 10,000 monthly Anlas + unlimited standard <=1024x1024 single images).
11. Grok (xAI)
Grok (now operated under SpaceX Super Intelligence LLC / SpaceXSI) is the least restrictive mainstream frontier model for current-events research, blunt debate, dark humor, and live web synthesis. On the October 2026 SpeechMap.AI Lab Leaderboard, xAI ranks #2 overall (81.7), far ahead of OpenAI (57.1) and Mistral (56.2), and Grok Voice 3.0 includes an explicit Unhinged voice persona alongside Grok 4.7's 500K token context window.
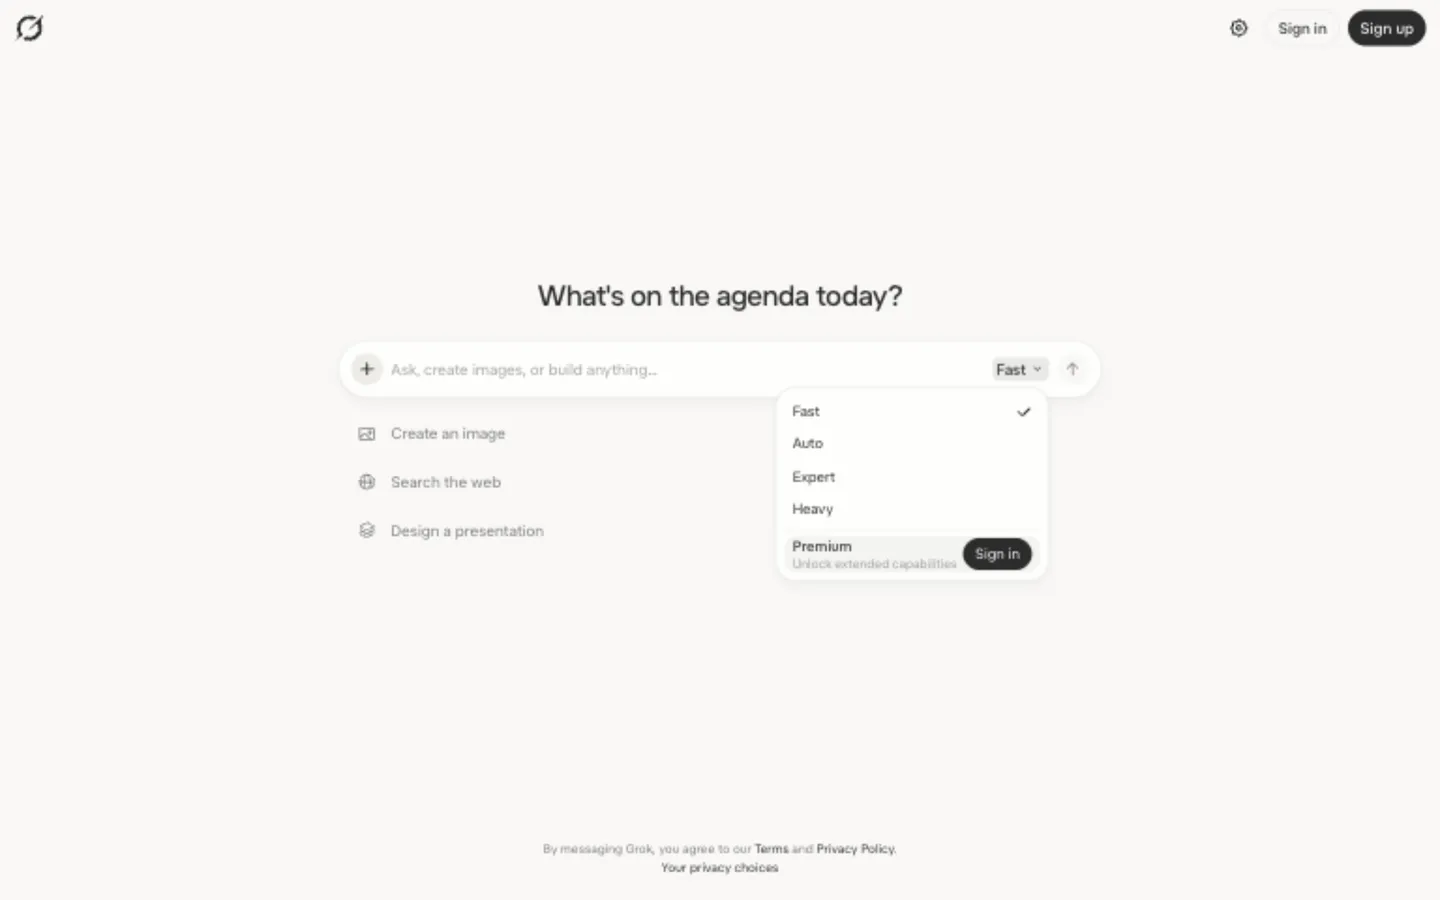
Keep three practical limits in mind from our live test: first, grok.com blocks your very first prompt behind an account sign-up modal (so Venice AI wins for anonymous use); second, switching from Fast non-reasoning mode to Expert / Reasoning mode raises sensitive-topic compliance dramatically (98.2% vs 62.6% on SpeechMap); and third, Grok is permissive on speech, satire, and gritty thriller prose, not an unrestricted adult image studio (Grok Imagine enforces hard blocks on explicit adult imagery and non-consensual likenesses).
Pros:
- Frontier reasoning intelligence (
Grok 4.7,500Kcontext) + live X and web search without preachy disclaimers - Unhinged Mode on
Grok Voice 3.0+ native 1080p audio-video clips on Super (Grok Imagine 1.5) - Team API (
$2/1M in · $6/1M out) supports Zero Data Retention (ZDR)
Cons:
- Hard account login gate before sending prompt #1
- $30/mo Premium tier needed for heavy
Grok 4.7usage; requires 24+ hours notice before renewal to cancel
Pricing: Free ($0 with login, capped), Plus $8/mo, Premium $30/mo (4x usage + full Grok 4.7), Super $100/mo (15x usage + 15s 1080p Imagine video), and Ultra $200/mo (50x usage).
12. HammerAI
HammerAI bridges the gap between local Ollama privacy and consumer character-chat convenience. If you do not want to configure Node.js for SillyTavern, HammerAI's native Desktop app (macOS Apple Silicon, Windows, Linux) bundles Ollama / llama.cpp into a one-click offline character studio with zero login required, while its browser app runs WebLLM / WebGPU models directly inside Chrome or Edge alongside 600 free encrypted cloud messages per day.
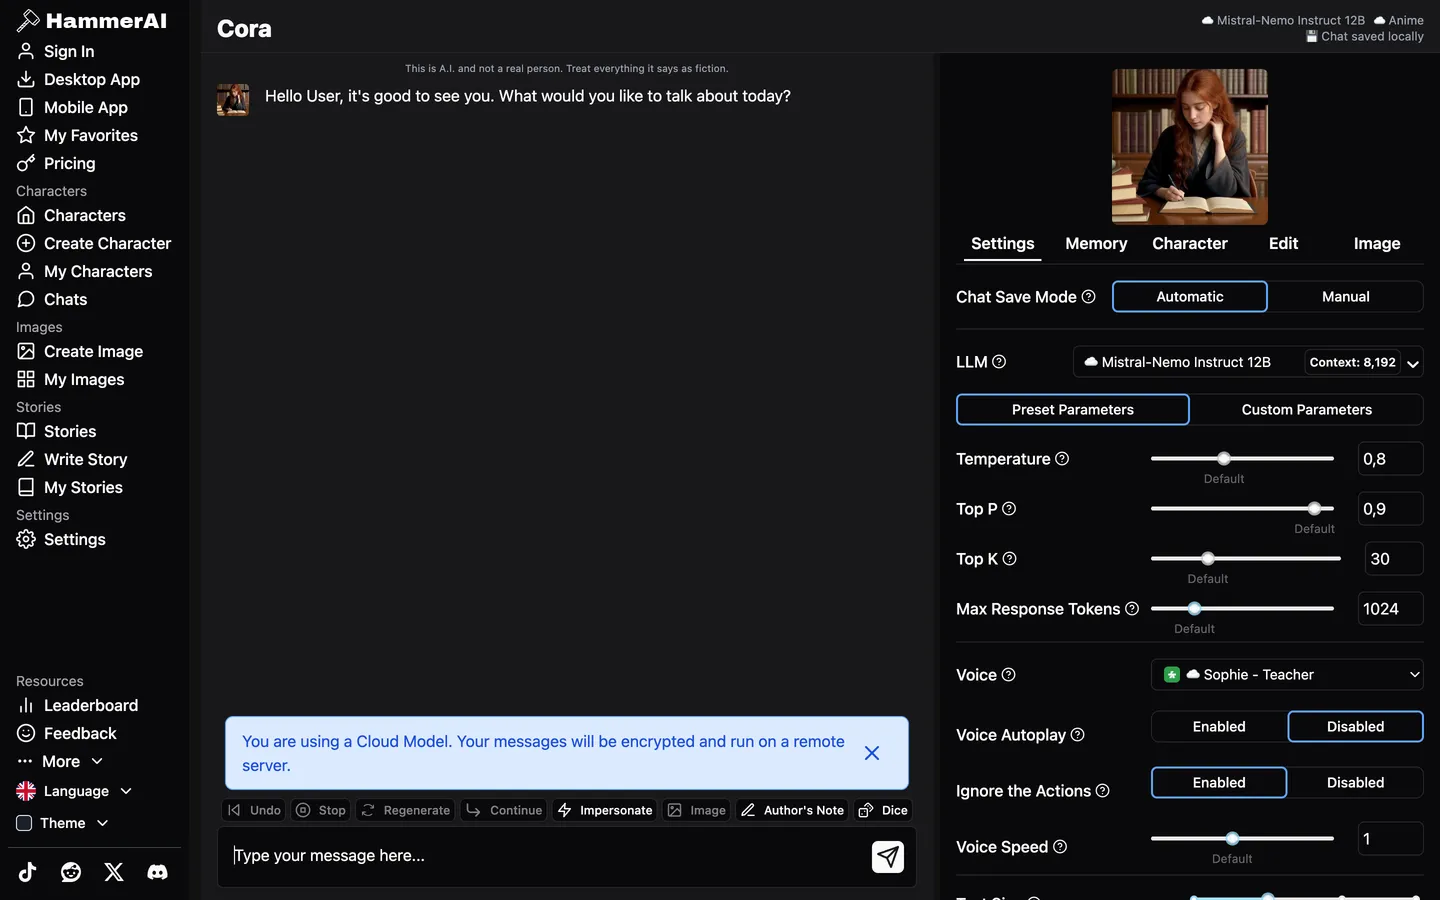
During browser testing, opening any character exposes right-hand controls for Mistral-Nemo Instruct 12B, context size (8,192 tokens free, up to 65,536 on Ultimate), temperature/top-K/top-P sliders, Universal Author's Notes, Lorebooks, and up to 10-character Group Chats, with chats saved directly inside your browser or local disk.
Pros:
- Unlimited free local LLMs on Desktop (zero account, zero ads) + 600 free cloud messages/day on web
- Supports WebGPU in-browser execution and external proxy routing (
localhost:1234/v1or OpenRouter) - Built-in Lorebooks, Group Chats, and SillyTavern character card imports
Cons:
- Less granular prompt-order customization than SillyTavern
- Hosted cloud subscriptions billed via GankNow are non-refundable
Pricing: Free ($0, unlimited local LLMs + 600 cloud msgs/day at 8K context). Cloud plans: Starter $9/mo (16K context + 150 images), Advanced $18/mo (32K context + 350 images), Ultimate $35/mo (64K context + 900 images).
13. aiAllure
aiAllure solves the biggest pricing annoyance in hosted visual companion apps: monthly media token depletion. Instead of rationing 100 tokens across images and video clips and nudging you into $9.99 top-up packs in week two, aiAllure locks one persistent companion face/identity across unfiltered chat, its VIVID Image Studio, Prime Video (with generated audio), and real-time Live Rooms with no monthly token meter on core paid features (AllureCoins only skip optional priority queues).
Free accounts can build a custom companion, generate one SFW preview image at a time, and test a 5-second video preview (initial Live Room setup queues for roughly 15 minutes on free accounts). Billing runs through Czech entity Novera Group s.r.o. via Visa, Mastercard, Apple Pay, and Google Pay.
Pros:
- No monthly token meter draining your balance on core companion photos and Prime Video
- Strong face and identity consistency across chat, VIVID images, and Live Rooms
- Free companion builder preview before subscribing
Cons:
- Higher month-to-month entry price ($19.90/mo) unless billed annually ($9.90/mo)
- No cryptocurrency payment option at checkout
Pricing: Starter $19.90/mo ($9.90/mo annual at $118.80/yr), Pro $39.90/mo ($19.90/mo annual), and Power $59.90/mo ($29.90/mo annual).
Try aiAllure14. OurDream AI
OurDream AI stands out for visual storytellers who want multi-character scene consistency rather than single-portrait selfies. Alongside its 11M+ community characters, OurDream ships a 40-page Comic Studio capable of keeping up to 3 custom characters consistent inside the same panel plus 10-scene stitched HD videos, and hands new signups 10 watermark-free HD images out of the gate.
One signup quirk caught during browser testing: OurDream's anti-abuse filter rejects custom or vanity email domains as disposable_domain, so register with a standard Gmail, iCloud, Outlook, or Google OAuth address. Card statements print discreetly as DREAMSTUDIOS.CO (Dream Studio USA, Inc.), and crypto is supported alongside Apple Pay and Google Pay.
Pros:
- 10 watermark-free HD images free at signup
- 40-page Comic Studio (up to 3 consistent characters per scene) + 10-scene stitched HD video
- Discreet
DREAMSTUDIOS.CObilling descriptor + crypto checkout
Cons:
- Rejects custom/personal domain emails at signup (use Gmail/Outlook/iCloud)
- High-res multi-scene video burns through the 1,000 monthly DreamCoins faster than still panels
Pricing: Free ($0, 10 HD images + limited chat). Premium $19.99/mo monthly or $9.99/mo billed annually ($119.88/yr, unlimited chat + 1,000 DreamCoins/mo).
15. DreamGen
DreamGen wears two hats in the uncensored AI ecosystem: an open-weight research lab on Hugging Face (dreamgen/lucid-v1-nemo 12B and opus-v1 7B/34B/70B) and a hosted V2 multi-character story and roleplay studio (Gemma 4 26B/31B, GLM 5.2, and Lucid). Instead of forcing everything into a single user-versus-bot thread, DreamGen lets you define world lore, character sheets, prose style rules, and plot beats between chapters so characters never slip into corporate "assistant-speak."
Pros:
- Publishes genuinely steerable open-weight
LucidandOpusmodels on Hugging Face alongside its cloud app - Built-in plot steering between turns keeps multi-character fiction coherent
- Generous no-card free tier with daily safety-net credits + prorated 2-day refund policy on paid plans
Cons:
- Free and Starter (
$7.83/mo) tiers cap context at4,000to5,000tokens (upgrade to Advanced for15Kor Pro for30K to 60K) - Focused on text fiction and scenario games rather than voice or video generation
Pricing: Free ($0, monthly + daily safety-net credits, 4K to 5K context). Starter $7.83/mo (5K context), Advanced $19.35/mo (15K context + unlimited base 1P models), and Pro $48.30/mo (30K to 60K context + unlimited all 1P models).
Uncensored AI comparison table (2026)
Every price, context window, and privacy architecture below reflects live browser verification on November 15, 2026:
| Tool | Best For | Hosting | Free Tier Cutoff | Paid Price (2026) | Max Context | True Privacy Level |
|---|---|---|---|---|---|---|
| Venice AI | Instant private ChatGPT replacement | Cloud (Browser DB + TEE) | 10 text + 15 img/day (no login) | $18/mo ($15/mo annual) | 128K to 1M | Local encrypted IndexedDB + 0-retention / TEE |
| Candy AI | Visual companions & Live Action video | Hosted Cloud | Few preview replies; media gated | $13.99/mo ($9.99 mo 1; $3.99/mo yr) | Persistent memory | Cloud-stored (pay via Crypto for 0 card trace) |
| Ollama | 1-command local CLI & API daemon | 100% Local (+ opt. Cloud) | Unlimited local ($0) | $0 local ($20/mo opt. Cloud) | 128K+ (RAM-bound) | Air-gapped offline ( localhost:11434) |
| SpicyChat AI | Free unfiltered roleplay ( 385K+ bots) | Hosted Cloud | Unlimited free text ( 4K ctx, queues) | $5.95 / $19.95 / $29.95/mo | 32K + Semantic 2.0 | Cloud-stored ( NDAI.CC + crypto billing) |
| LM Studio | Desktop GUI for GGUF & Apple MLX | 100% Local (+ opt. ZDR) | Unlimited local ($0) | $0 personal & work use | 128K+ (RAM-bound) | Air-gapped offline ( localhost:1234) |
| OpenRouter | Pay-per-token 24B to 405B API | Multi-Host Cloud API | 50 req/day on 14 :free models | $0.04 to $3/1M + 5.5% load fee | 1.05M tokens | ZDR filter on paid credits ( :free may log) |
| GirlfriendGPT | 40,000+ ready-made scenarios | Hosted Cloud | SFW-only preview | $15 / $35 / $50/mo ($12/mo yr) | 8x memory (Elite) | Cloud-stored ( NDAI.CHAT + crypto billing) |
| SillyTavern | Character cards, lorebooks & prefill | Self-Hosted UI | 100% Free ( AGPL-3.0) | $0 (BYO local or API) | Backend-dependent | 100% local UI ( 127.0.0.1:8000) |
| KoboldCpp | Single-file zero-install GGUF + Flux | 100% Local | 100% Free ( AGPL-3.0) | $0 | 32K+ w/ Context Shift | Air-gapped single binary ( localhost:5001) |
| NovelAI | Encrypted long-form fiction & anime | Encrypted Cloud | 50 text + 30 img (email trial) | $10 / $15 / $25/mo (Opus) | 28,672 tokens | Client-side encrypted stories; 0 img storage |
| Grok (xAI) | Permissive frontier search & reasoning | Hosted Cloud | Capped free tier (login required) | $8 / $30 / $100/mo | 500K (Grok 4.7) | Incognito mode; Team API supports ZDR |
| HammerAI | WebGPU browser & zero-login desktop RP | Local + Cloud | Unl. local + 600 cloud msgs/day | $0 local; $9 to $35/mo cloud | 8K free to 64K | On-device local storage; encrypted cloud |
| aiAllure | Token-free companion images & video | Hosted Cloud | Free build + SFW preview | $19.90 to $59.90/mo ($9.90/mo yr) | Persistent memory | Cloud-stored ( Novera Group s.r.o.) |
| OurDream AI | 40-page multi-character Comic Studio | Hosted Cloud | 10 free HD images + trial chat | $19.99/mo ($9.99/mo annual) | 3-char consistency | Cloud-stored ( DREAMSTUDIOS.CO + crypto) |
| DreamGen | Plot-steered multi-character stories | Open Weights + Cloud | Free monthly + daily credits ( 4K) | $7.83 / $19.35 / $48.30/mo | 30K to 60K (Pro) | Local via HF Lucid weights, or Cloud |
Local uncensored LLM hardware and VRAM guide
Most uncensored AI roundups wave vaguely at "running Llama locally" without telling you whether a model will crash your laptop. Thanks to llama.cpp mixed-precision Q4_K_M quantization (~4.85 bits per weight), local model weights shrink by roughly 70% compared to 16-bit FP16 while adding just +0.1754 perplexity on an 8B model and +0.1366 perplexity on a 70B model.
Match your GPU VRAM or Apple Silicon Unified Memory to the exact verified November 2026 open-weight checkpoints below (leaving 1.5 to 4 GiB of headroom for your 8K to 16K KV context cache):
| Your Hardware Tier | Exact Q4_K_M Weight Size | Best 2026 Uncensored / Abliterated Models | Why Pick This Checkpoint |
|---|---|---|---|
8 GB VRAM GPU or 16 GB Mac | 2.32 GiB to 5.24 GiB | • dphn/Dolphin3.0-Llama3.1-8B-GGUF (4.58 GiB)• lukey03/Qwen3.5-9B-abliterated-GGUF (5.24 GiB)• mlabonne/gemma-3-4b-it-abliterated-GGUF (2.32 GiB) | 4.3M+ Ollama pulls on dolphin3; runs at 45 to 90+ tokens/sec on M1-M4 Macs for general chat, coding, and tool calling |
12 to 16 GB VRAM (RTX 3060/4070) or 24 GB Mac | 6.80 GiB to 8.37 GiB | • dphn/dolphin-2.9.3-mistral-nemo-12b-gguf (6.96 GiB)• anthracite-org/magnum-v4-12b-gguf (6.96 GiB)• DeepSeek-R1-Distill-Qwen-14B-abliterated-v2 (8.37 GiB) | Mistral-Nemo 12B (128K native context) and Magnum v4 12B avoid robotic phrasing; R1-14B adds unfiltered <think> reasoning |
24 GB VRAM (RTX 3090/4090) or 32 to 36 GB Mac | 13.35 GiB to 18.49 GiB | • dphn/Dolphin-Mistral-24B-Venice-Edition (13.35 GiB)• TheDrummer/Cydonia-24B-v4.3-GGUF (13.35 GiB)• huihui-ai/Huihui-Qwen3.8-27B-abliterated-GGUF (15.41 GiB)• Huihui-Qwen3.6-35B-A3B-abliterated-MTP (MoE) | The 2026 local sweet spot. Qwen3.6-35B-A3B (5.04M monthly HF downloads) activates only 3B params per token for 60 to 120 tok/s speeds |
48 GB+ Dual GPU or 64 to 128 GB Mac Studio | 39.60 GiB to 44.16 GiB | • anthracite-org/magnum-v4-72b-gguf (44.16 GiB)• NousResearch/Hermes-4-70B (~40 GiB)• DeepSeek-R1-Distill-Llama-70B-abliterated (39.60 GiB) | Near-frontier prose nuance, multi-character tracking, and security/code analysis completely air-gapped on workstation hardware |
Rule of thumb when picking between Abliterated vs Fine-Tuned weights: Choose an abliterated model (Huihui-Qwen3.8-27B, Qwen3.6-35B-A3B, DeepSeek-R1-Distill) when you need sharp coding, math, OSINT, or reasoning on brand-new architectures. Choose an uncensored SFT or roleplay fine-tune (Dolphin 3.0, Dolphin-Mistral-24B Venice Edition, Cydonia 24B, Magnum v4, DreamGen Lucid) when you want expressive fiction or roleplay without clinical corporate phrasing.
Cloud API vs 100% local LLM privacy
"Uncensored" does not automatically mean private. Several hosted sites advertising "no filters" log plaintext prompts on rented cloud GPUs, retain transcripts for abuse review, or print recognizable brand names on your credit card statement.
Separate every tool into three cryptographic trust tiers before typing anything sensitive:
- Tier 1:
100% LOCAL LLM(Air-Gapped Hardware Trust). Running Ollama, LM Studio, KoboldCpp, or HammerAI Desktop with localGGUForMLXweights keeps every token inside your own RAM and SSD. Turn off Wi-Fi and verify it yourself: zero bytes leave your machine. - Tier 2: Client-Encrypted, TEE, or ZDR
CLOUD APIRouting. NovelAI encrypts story blobs in your browser before storage. Venice AI keeps chat history in local encryptedIndexedDBand offers 13 TEE/E2EE models running inside hardware enclaves. OpenRouter (on funded Standard accounts withdata_collection: "deny") restricts routing to verified Zero Data Retention (ZDR) inference hosts. - Tier 3: Hosted Plaintext Cloud Apps. Companion and community bot platforms (Candy AI, SpicyChat AI, GirlfriendGPT, aiAllure, OurDream AI) store your chats and generated media on their servers so companion memory syncs across devices. Treat them like any hosted social app: never paste real names, work documents, or private photos, pair browser use with a no-logs VPN if your ISP or region enforces UK Online Safety Act
HTTP 451geo-blocks, and check statement descriptors (NDAI.CC,NDAI.CHAT,DREAMSTUDIOS.CO, or use crypto on Candy AI to avoidEverAI candy.ai MT).
Uncensored AI image and video options in 2026
Hosted visual platforms tightened policies sharply over the past year: OpenAI retired legacy DALL-E endpoints in May 2026, and Tensor.Art switched its main domain to SFW-only on November 27, 2025 (spinning mature generation off onto TensorHub). In late 2026, unfiltered visual generation splits cleanly between local open weights and dedicated paid studios:
- Local unfiltered image & video stack (
$0per render): Pair ComfyUI, Stable Diffusion WebUI Forge, or KoboldCpp (v1.124.2) withSDXL/Pony V6 XL(8 GB+VRAM),Flux.1+ communityLoRAadapters (12 to 24 GBVRAM), andWan 2.2orLTX 2.3(16 GB+VRAM) for local text-to-video and image-to-video clips. See our broader AI art generator and AI video generator benchmarks for workflow speeds. - Hosted browser studios (zero GPU setup): Venice AI Pro ($18/mo) unlocks 1,000 unfiltered images/day plus credit-metered
Wan 3.0andKling V3clips; NovelAI Opus ($25/mo) includes unlimited single standard renders on Diffusion V5; Candy AI animates chat replies via Live Action; aiAllure includes VIVID Images and Prime Video without a monthly token meter; and OurDream AI builds 40-page multi-character comics and 10-scene stitched HD videos.
Frequently asked questions
What does uncensored AI actually mean?
An uncensored AI removes over-eager corporate alignment filters, preachy moralizing disclaimers, and post-generation topic blocks so the model follows your SYSTEM prompt directly. Developers, novelists, and researchers use uncensored models (Dolphin 3.0, Hermes 4, Huihui-Qwen3.8-abliterated, Venice Uncensored 1.2) for dark thriller fiction, cybersecurity reverse engineering, medical or legal analysis, and private character roleplay without hitting false refusals.
What is the best completely free uncensored AI chatbot in 2026?
For zero-login private cloud chat, Venice AI gives 10 text prompts and 15 image prompts per day free on Venice Uncensored 1.2 with no email required. For unlimited free character roleplay in a browser, SpicyChat AI offers unlimited messages across 385,949+ characters at 4K context. For 100% unlimited offline use with zero limits forever, install Ollama or LM Studio and run dolphin3 locally for $0.
How does abliteration uncensor an LLM without retraining it?
Based on NeurIPS 2024 research by Arditi et al. (arXiv:2406.11717), safety refusal in chat LLMs is controlled by a single one-dimensional vector in the residual stream. Abliteration measures activation differences across ~128 harmful and ~128 harmless prompts, isolates that refusal vector, and mathematically projects it out of the model's weight matrices in minutes without full supervised fine-tuning. Adding 1 epoch of DPO "heals" any slight perplexity dip.
Is it better to run uncensored AI locally or in the cloud?
Run locally (Ollama, LM Studio, KoboldCpp) if you want cryptographic air-gapped privacy, zero monthly bills, and immunity from sudden platform policy changes, provided you have at least 8 GB of GPU VRAM or 16 GB of Apple Silicon RAM. Use cloud (Venice AI, OpenRouter with ZDR, NovelAI, or Candy AI) if you chat from your phone, want 70B to 405B+ frontier intelligence without a workstation, or want integrated voice and video companions.
How much RAM or VRAM do I need to run an uncensored LLM locally?
Using GGUF Q4_K_M quantization (~70% smaller than FP16), an 8B to 9B model (Dolphin 3.0 8B, Qwen 3.5 9B Abliterated) takes 4.6 to 5.3 GiB on disk and runs smoothly on an 8 GB GPU or 16 GB Mac. Mid-size 24B to 27B models (Dolphin-Mistral-24B, Huihui-Qwen3.8-27B) need a 24 GB GPU or 32 GB Mac, and 70B to 72B models (Magnum v4 72B, Hermes 4 70B) need 48 GB+ VRAM or a 64 GB Mac Studio.
Did OpenAI ever launch ChatGPT's Adult Mode?
No. After teasing an age-verified "Adult Mode" in October 2025 for December 2025 and pushing it to Q1 2026, OpenAI confirmed a second indefinite delay with no release date on March 7, 2026. ChatGPT continues to enforce strict input and output moderation across both free and $20 to $200/mo plans.
Why not just use a jailbreak prompt on ChatGPT or Claude?
Prompt-level jailbreaks (DAN templates or cipher wrappers) break constantly because frontier labs patch external output classifiers asynchronously without updating model weights, and repeated moderation flags can suspend your paid API or Plus account. Switching to an abliterated open-weight model (Ollama, OpenRouter) or Venice Uncensored gives stable, repeatable compliance from standard system prompts.
Are hosted uncensored AI chatbots private?
Only if the architecture proves it mathematically. NovelAI encrypts stories client-side in your browser, Venice AI stores chats in local browser IndexedDB and offers hardware TEE enclaves, and OpenRouter enforces Zero Data Retention (ZDR) on funded accounts (not on :free models). Standard companion apps (Candy AI, SpicyChat, GirlfriendGPT) store chats on cloud servers to power cross-device companion memory.
Are uncensored AI tools legal to use?
Yes. Downloading open-weight LLMs (Apache 2.0, Llama, or Qwen licenses), removing safety refusal vectors via abliteration, and using unfiltered chat or fiction studios is legal in the US, EU, and most jurisdictions. Liability attaches to what you generate or distribute: illegal material such as CSAM, non-consensual intimate imagery ("nudify" apps), fraud, and actionable violence remains illegal whether generated locally or in the cloud.
Which uncensored AI API is best for SillyTavern in 2026?
OpenRouter is the best pay-per-token cloud backend for SillyTavern: fund $5 to unlock Zero Data Retention routing, then point SillyTavern at cognitivecomputations/dolphin-mistral-24b-venice-edition ($0.20/$0.90 per 1M), thedrummer/cydonia-24b-v4.1 ($0.30/$0.50), sao10k/l3.1-euryale-70b ($0.85/$0.85), or nousresearch/hermes-4-405b ($1.00/$3.00). For a $0 local backend, connect SillyTavern to Ollama (127.0.0.1:11434) or KoboldCpp (127.0.0.1:5001).